
Dataset, Models and Paper from ComicsPAP: understanding comic strips by picking the correct panel
AI & ML interests
Multimodal AI, Document Understanding, Reading Systems.
Recent Activity
View all activity
Papers

ICDAR2026 Competition on Multimodal Reasoning over Documents in Multiple Domains
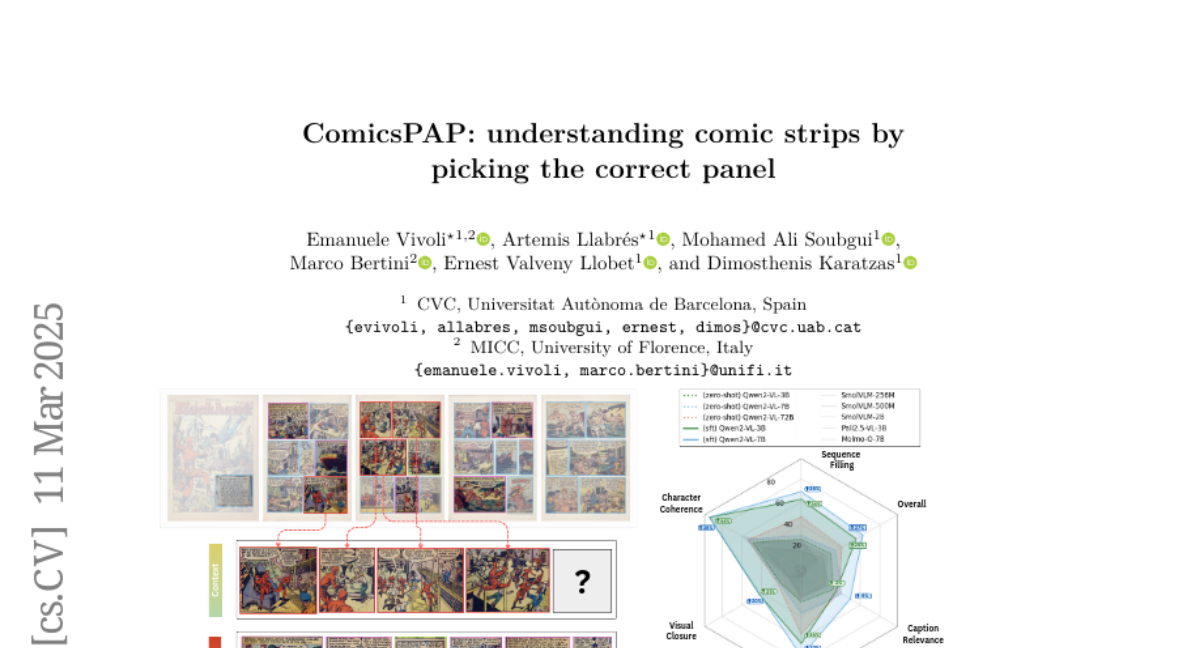
ComicsPAP: understanding comic strips by picking the correct panel
Organization Card
Vision, Language, and Reading Group
At the Computer Vision Center (CVC) in Barcelona, Spain.
The VLR research team conducts fundamental research and technology transfer at the frontier between vision, language and reading systems. We devise reading systems for text in the wild, and incorporate scene text semantics in a multitude of computer vision tasks such as captioning, visual question answering, cross-modal retrieval, fine-grained classification, etc. In parallel, we advance document understanding with a special interest in end-to-end approaches for Document Visual Question Answering.
models 5

VLR-CVC/CVC-Qwen3.5-35B-A3B
Image-Text-to-Text • 35B • Updated • 1
VLR-CVC/CVC-Qwen3.5-2B-SFT
Image-Text-to-Text • 2B • Updated • 2
VLR-CVC/CVC-Qwen3.5-35B-A3B-SFT
Image-Text-to-Text • 35B • Updated
VLR-CVC/Qwen2.5-VL-7B-Instruct-lora-ComicsPAP
Updated
VLR-CVC/Qwen2.5-VL-3B-Instruct-lora-ComicsPAP
Updated • 4