


Update README.md
Browse files
README.md
CHANGED
|
@@ -11,7 +11,7 @@ tags:
|
|
| 11 |
|
| 12 |
# SAMBA
|
| 13 |
|
| 14 |
-
EEG representation models. [Code](https://github.com/Jiazhen-Hong/SAMBA) · [Paper](https://arxiv.org/abs/2511.18571)
|
| 15 |
|
| 16 |
SAMBA was developed during my 2025 internship at Emotiv. The original checkpoints are no longer available, so we retrained both models. SAMBA-100s follows the original training method with a rebuilt TUAB pipeline and validation split. SAMBA-2s adds HBN, Muse, and DICE to the Emotiv data for greater electrode-layout diversity.
|
| 17 |
|
|
@@ -28,6 +28,14 @@ Both models use 128 Hz EEG. The names indicate the pretraining window; the encod
|
|
| 28 |
|
| 29 |
¹ Alpha, Attention, Crowdsource, DriverDistraction, and STEW.
|
| 30 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 31 |
## Usage
|
| 32 |
|
| 33 |
Requires a compatible CUDA system.
|
|
|
|
| 11 |
|
| 12 |
# SAMBA
|
| 13 |
|
| 14 |
+
EEG representation models. [Project website](https://samba.dcode.ai/) · [Code](https://github.com/Jiazhen-Hong/SAMBA) · [Paper](https://arxiv.org/abs/2511.18571)
|
| 15 |
|
| 16 |
SAMBA was developed during my 2025 internship at Emotiv. The original checkpoints are no longer available, so we retrained both models. SAMBA-100s follows the original training method with a rebuilt TUAB pipeline and validation split. SAMBA-2s adds HBN, Muse, and DICE to the Emotiv data for greater electrode-layout diversity.
|
| 17 |
|
|
|
|
| 28 |
|
| 29 |
¹ Alpha, Attention, Crowdsource, DriverDistraction, and STEW.
|
| 30 |
|
| 31 |
+
## Learned EEG spatial weights
|
| 32 |
+
|
| 33 |
+
SAMBA uses electrode coordinates to learn how to combine EEG channels. These examples from the paper show the learned spatial weights across three tasks.
|
| 34 |
+
|
| 35 |
+
| Eyes open vs. closed | Driver distraction | Motor imagery |
|
| 36 |
+
|:---:|:---:|:---:|
|
| 37 |
+
| 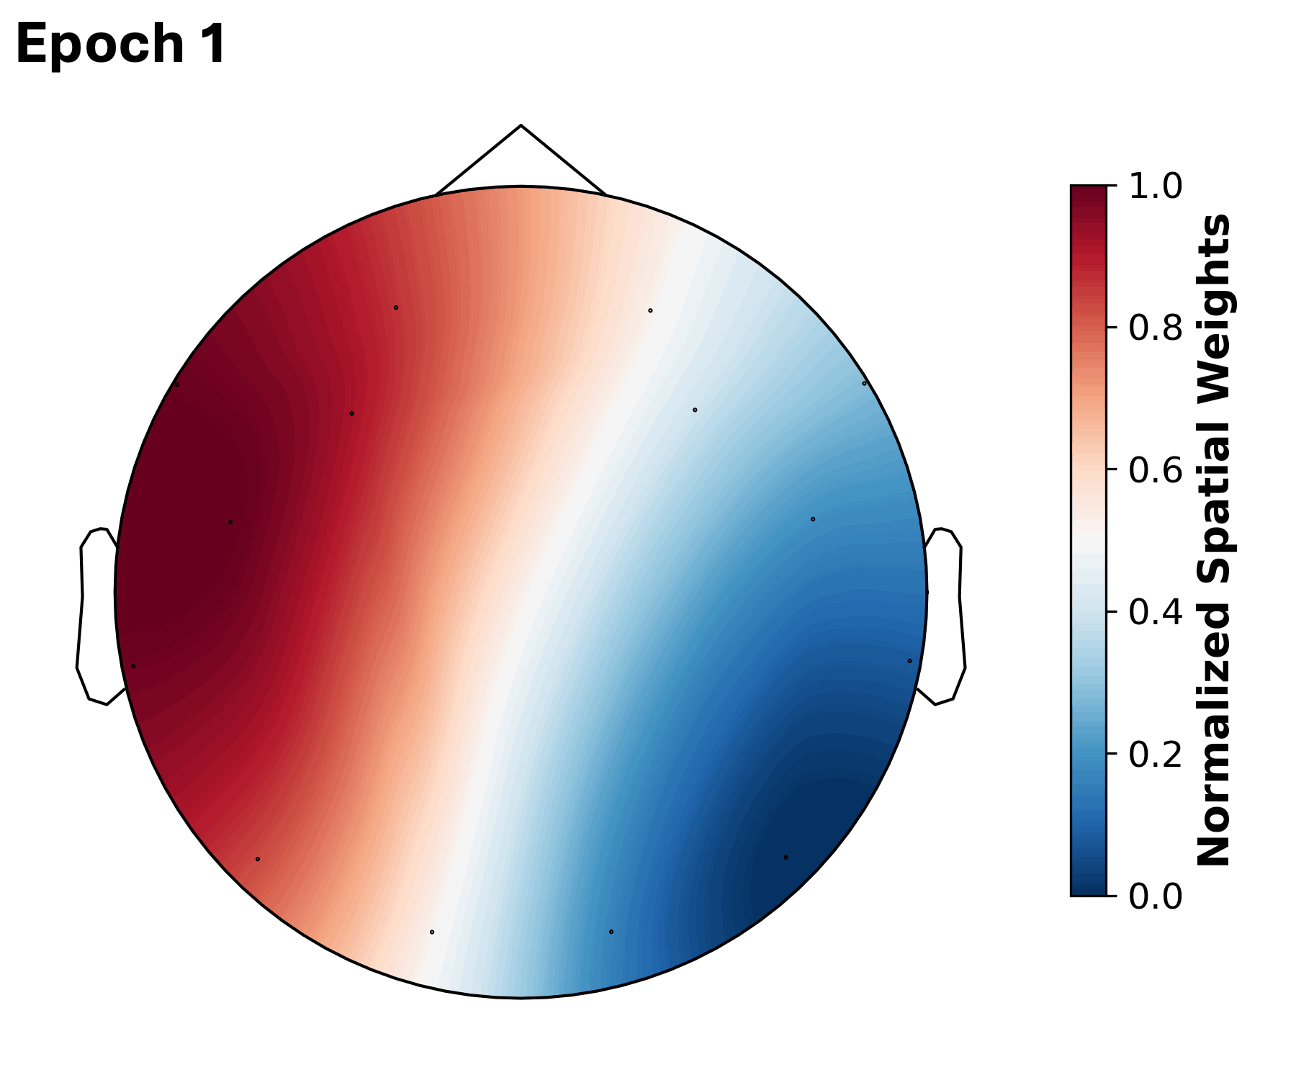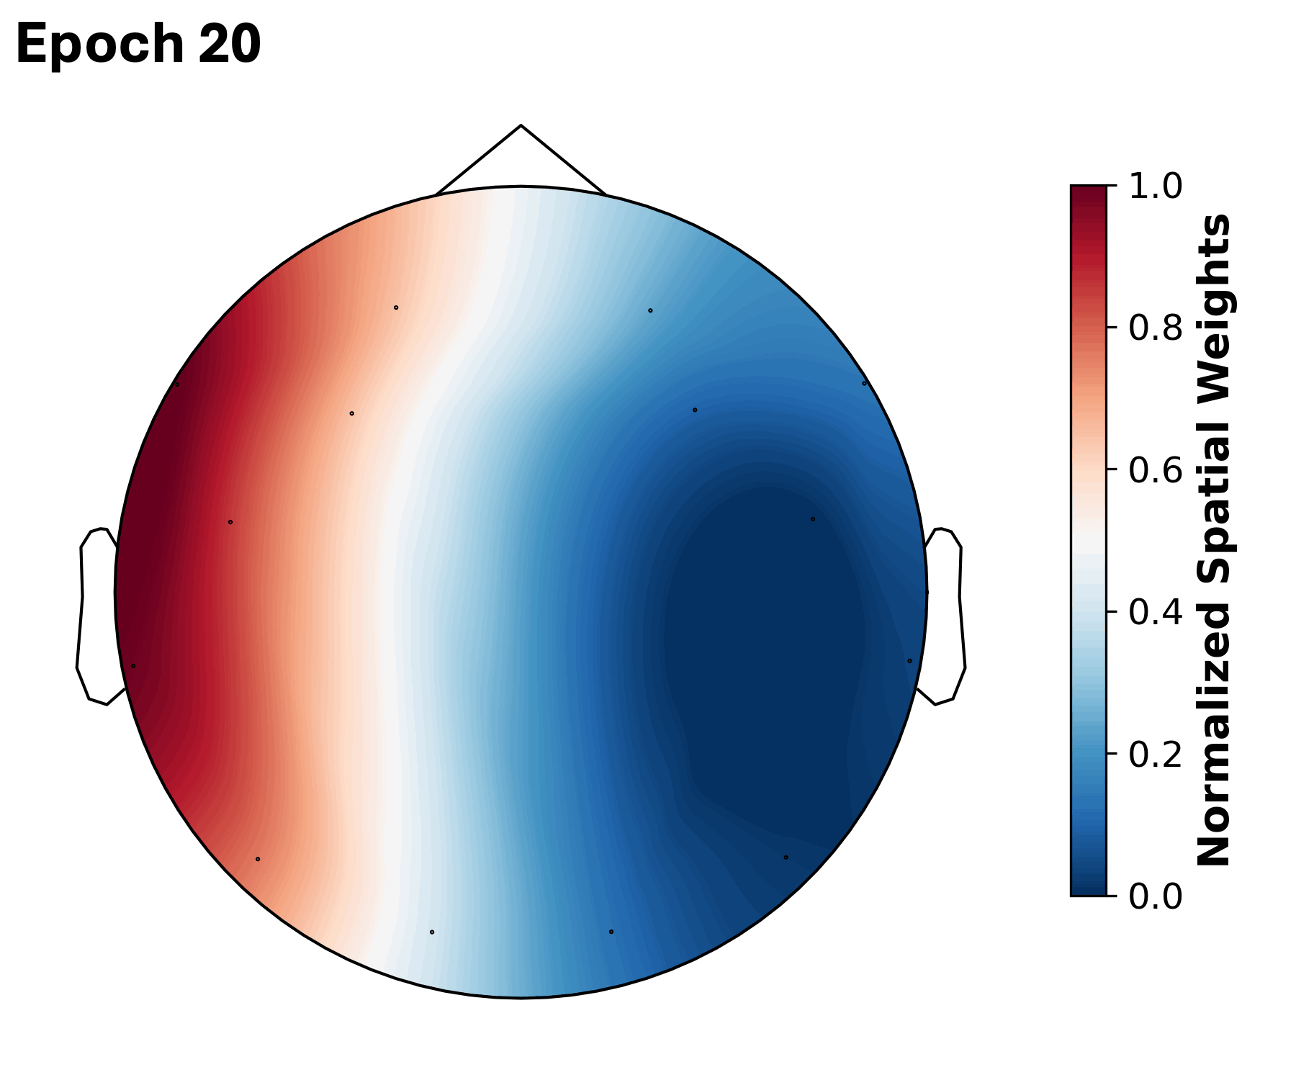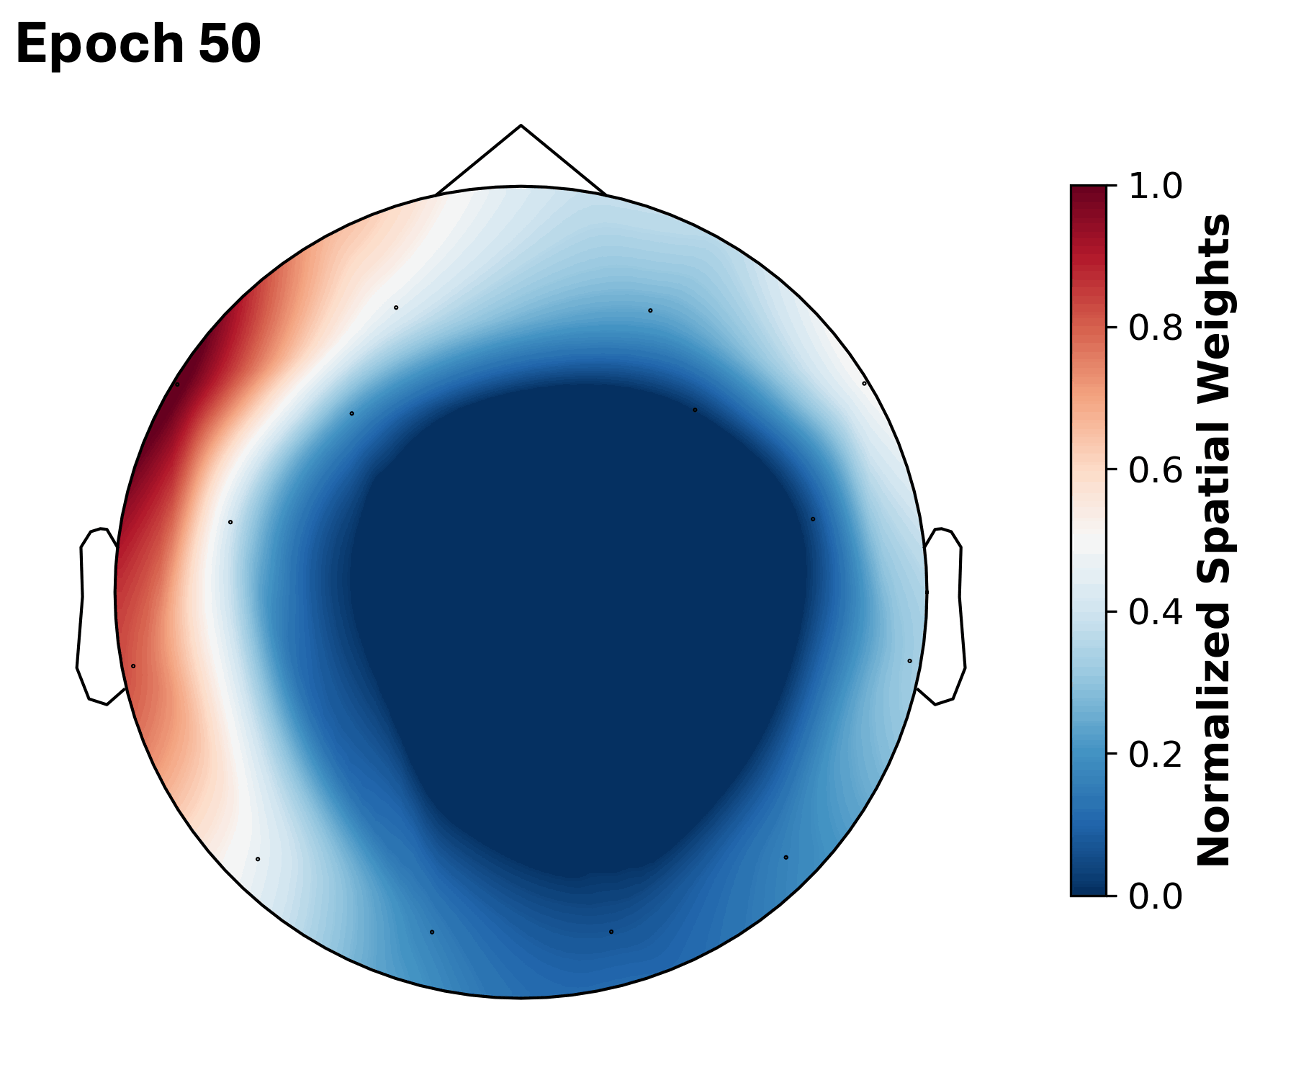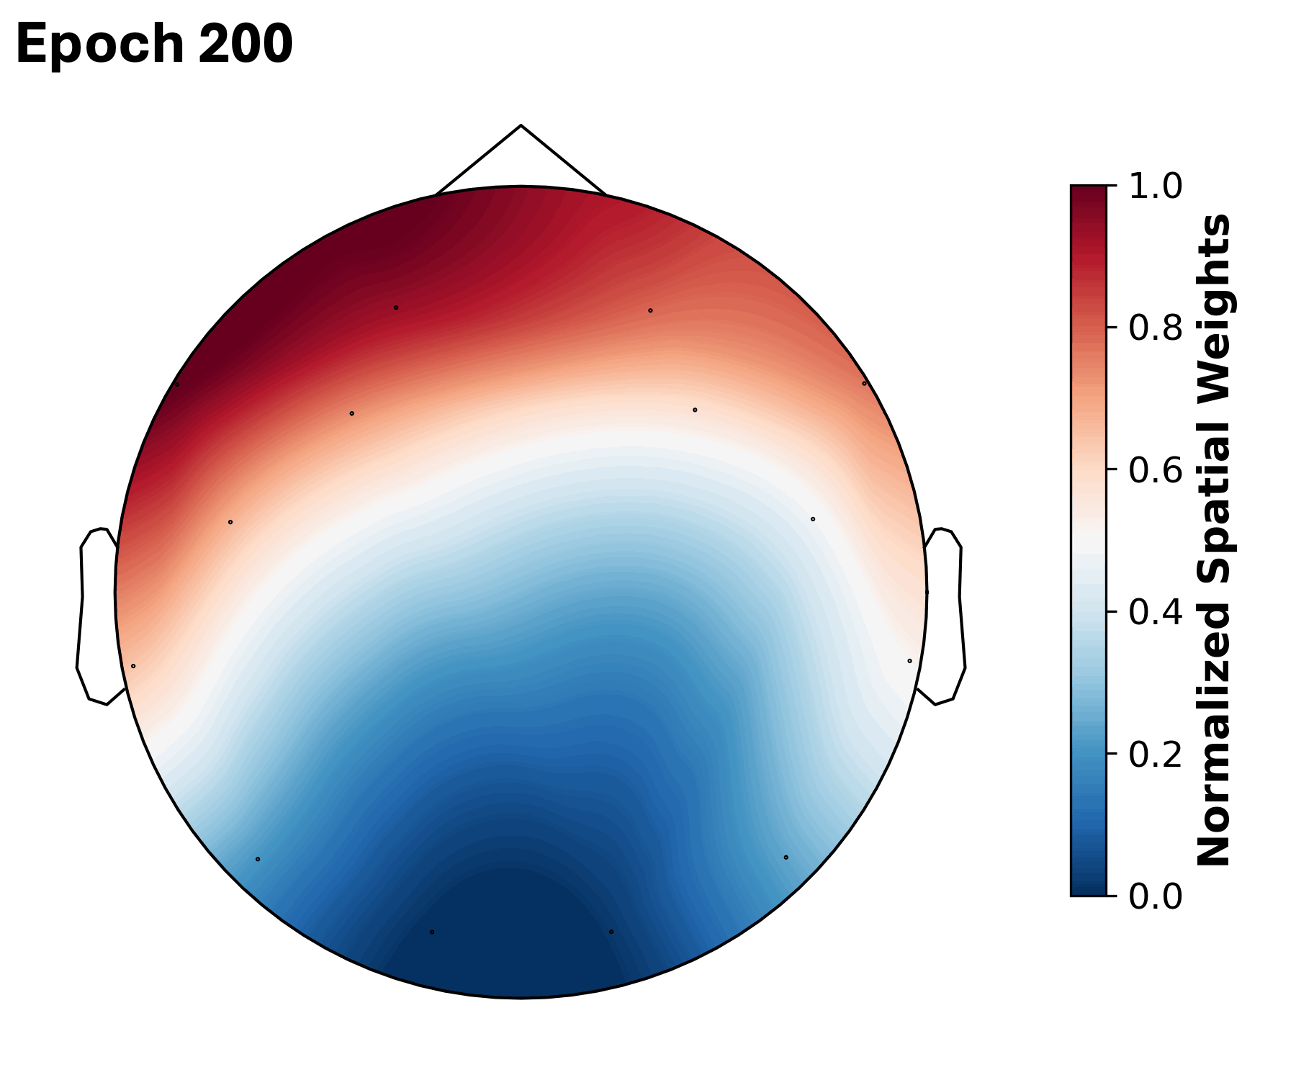 | 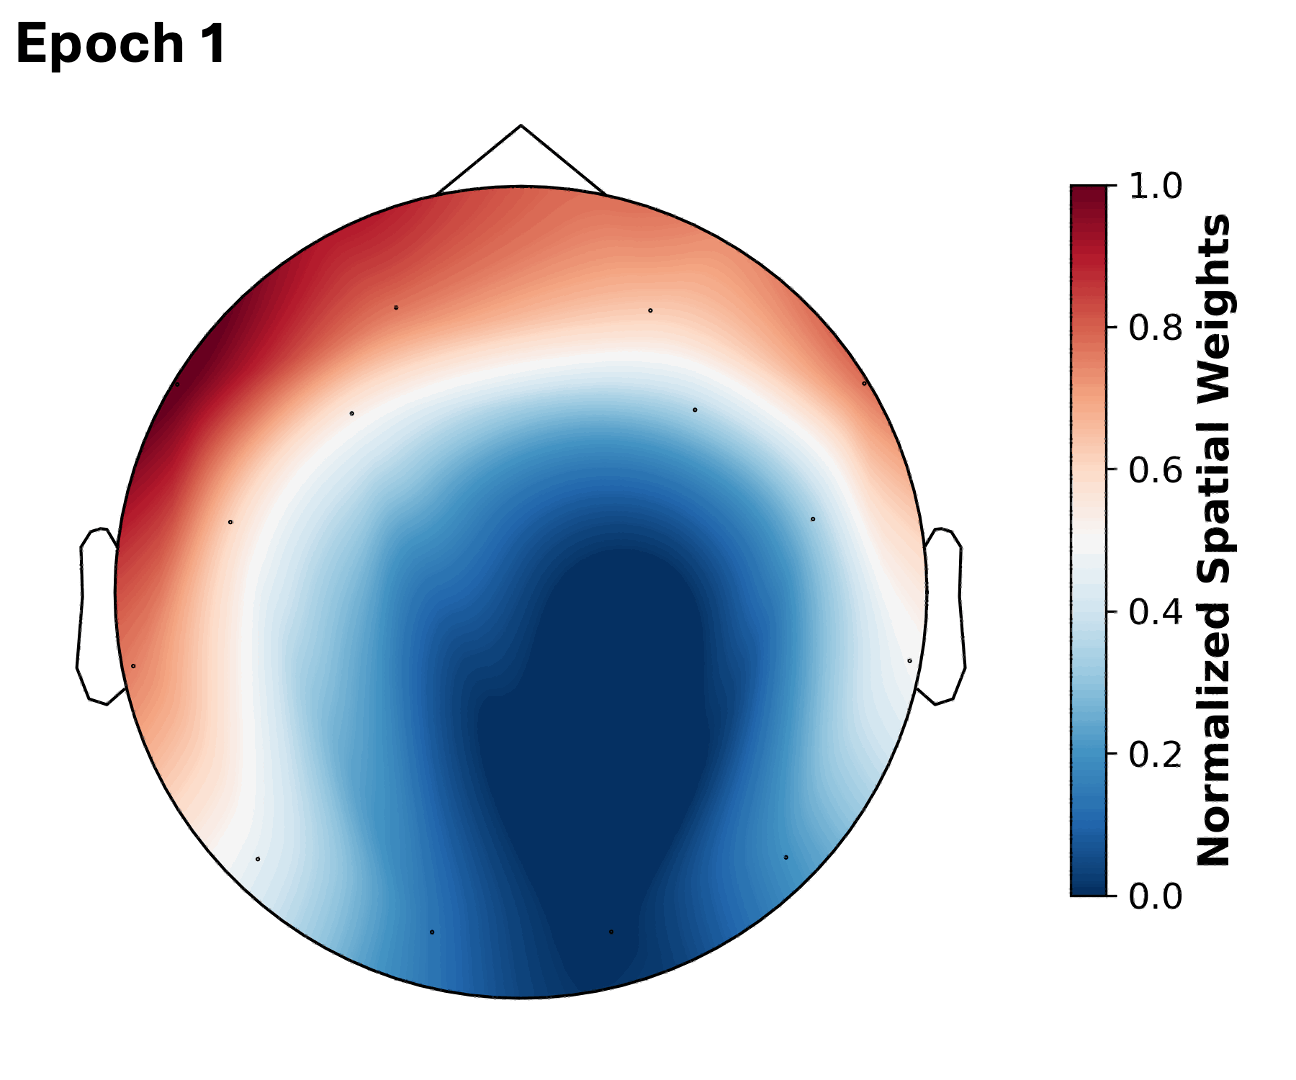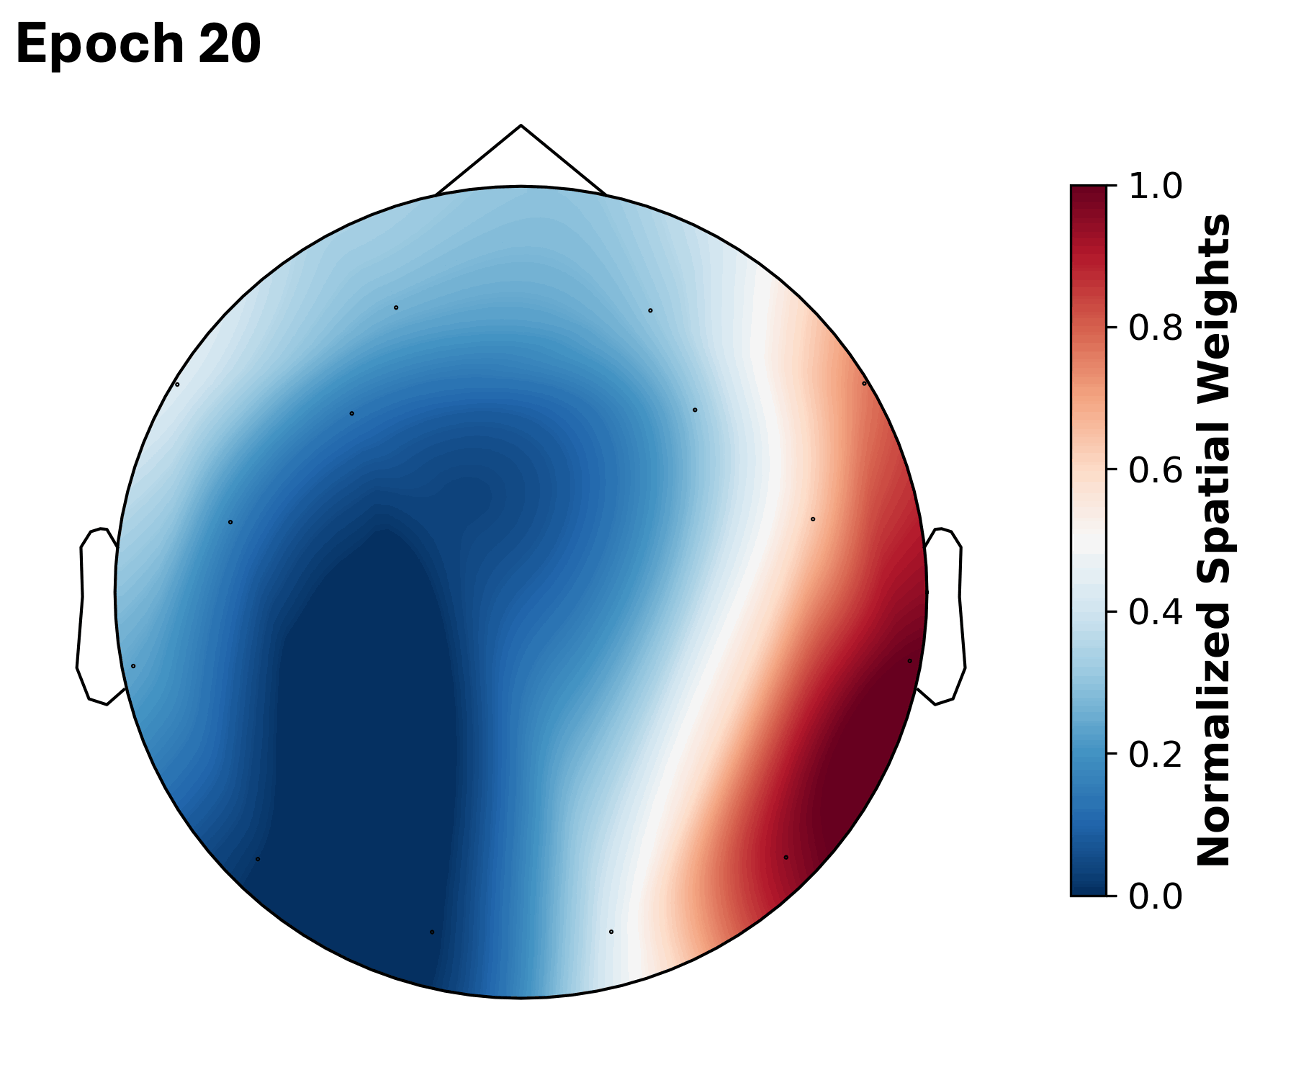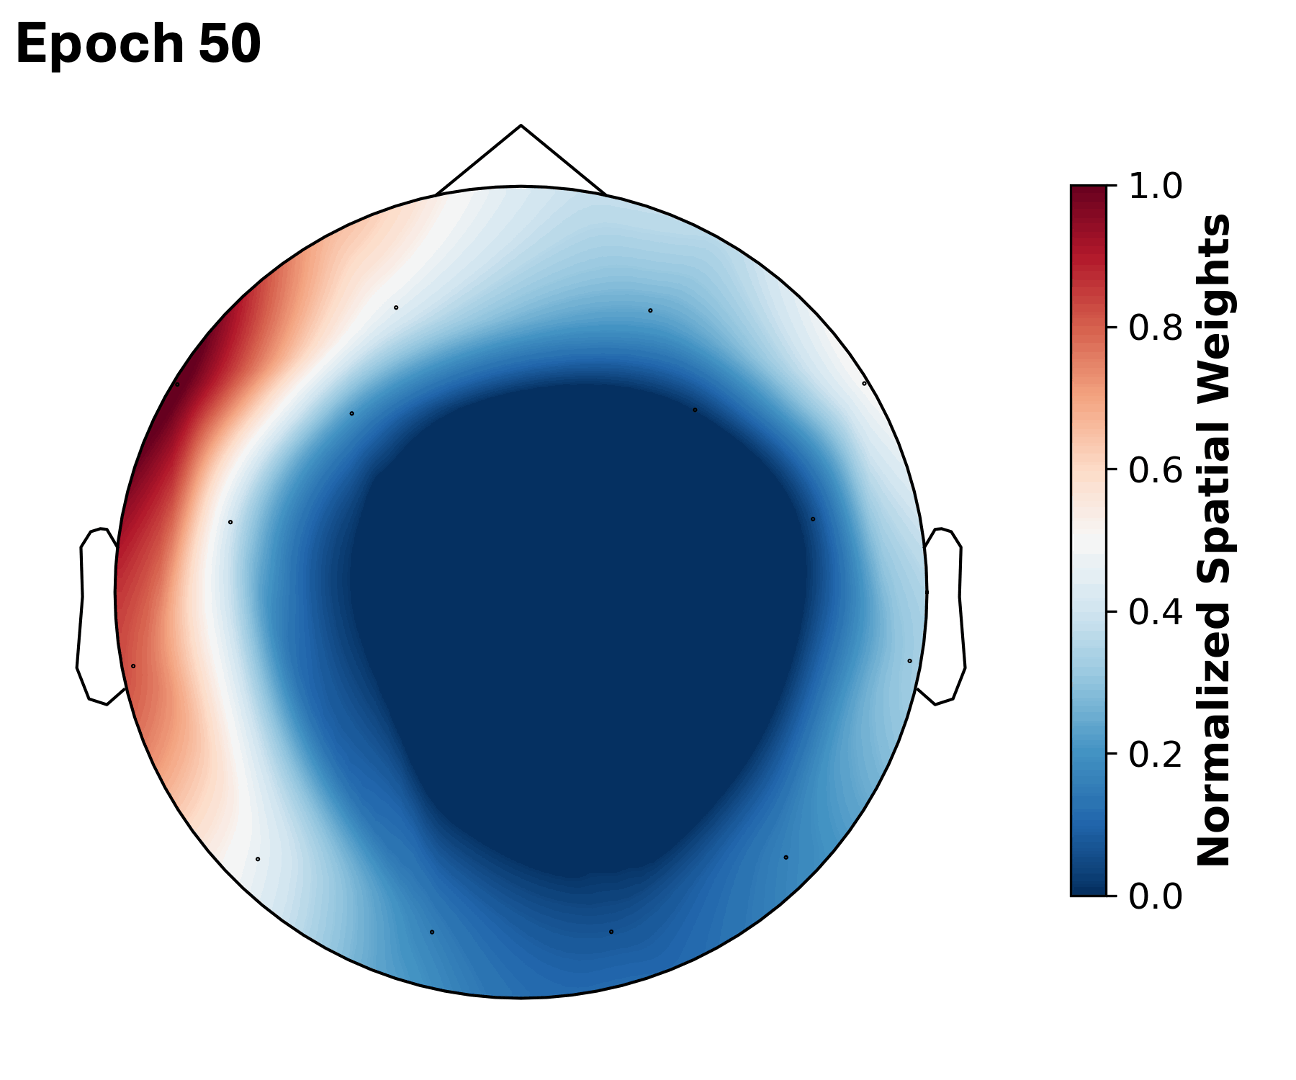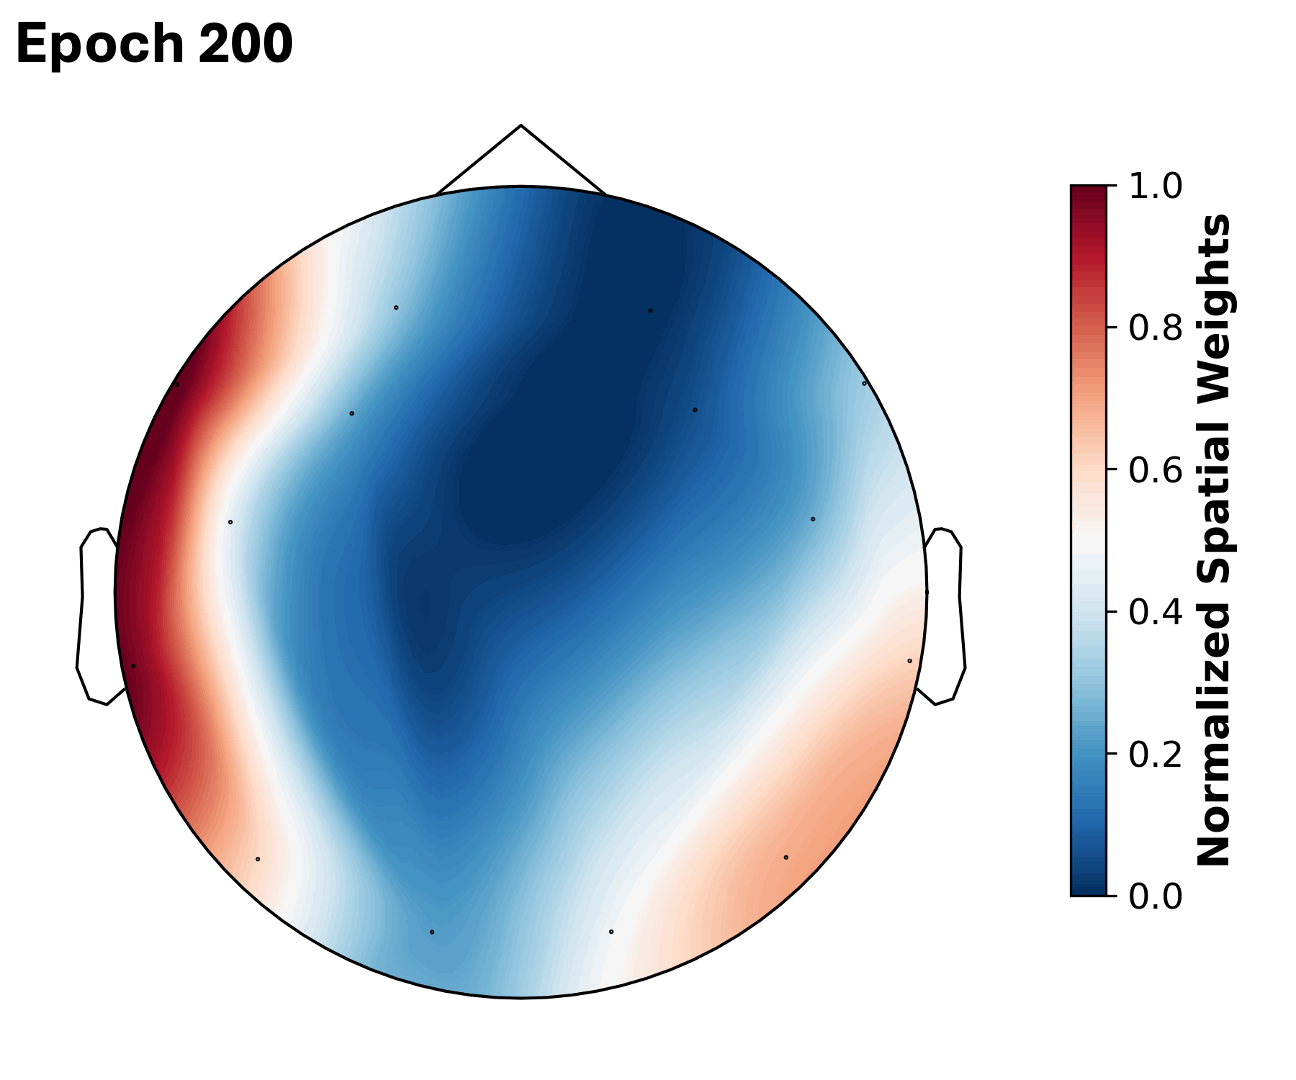 | 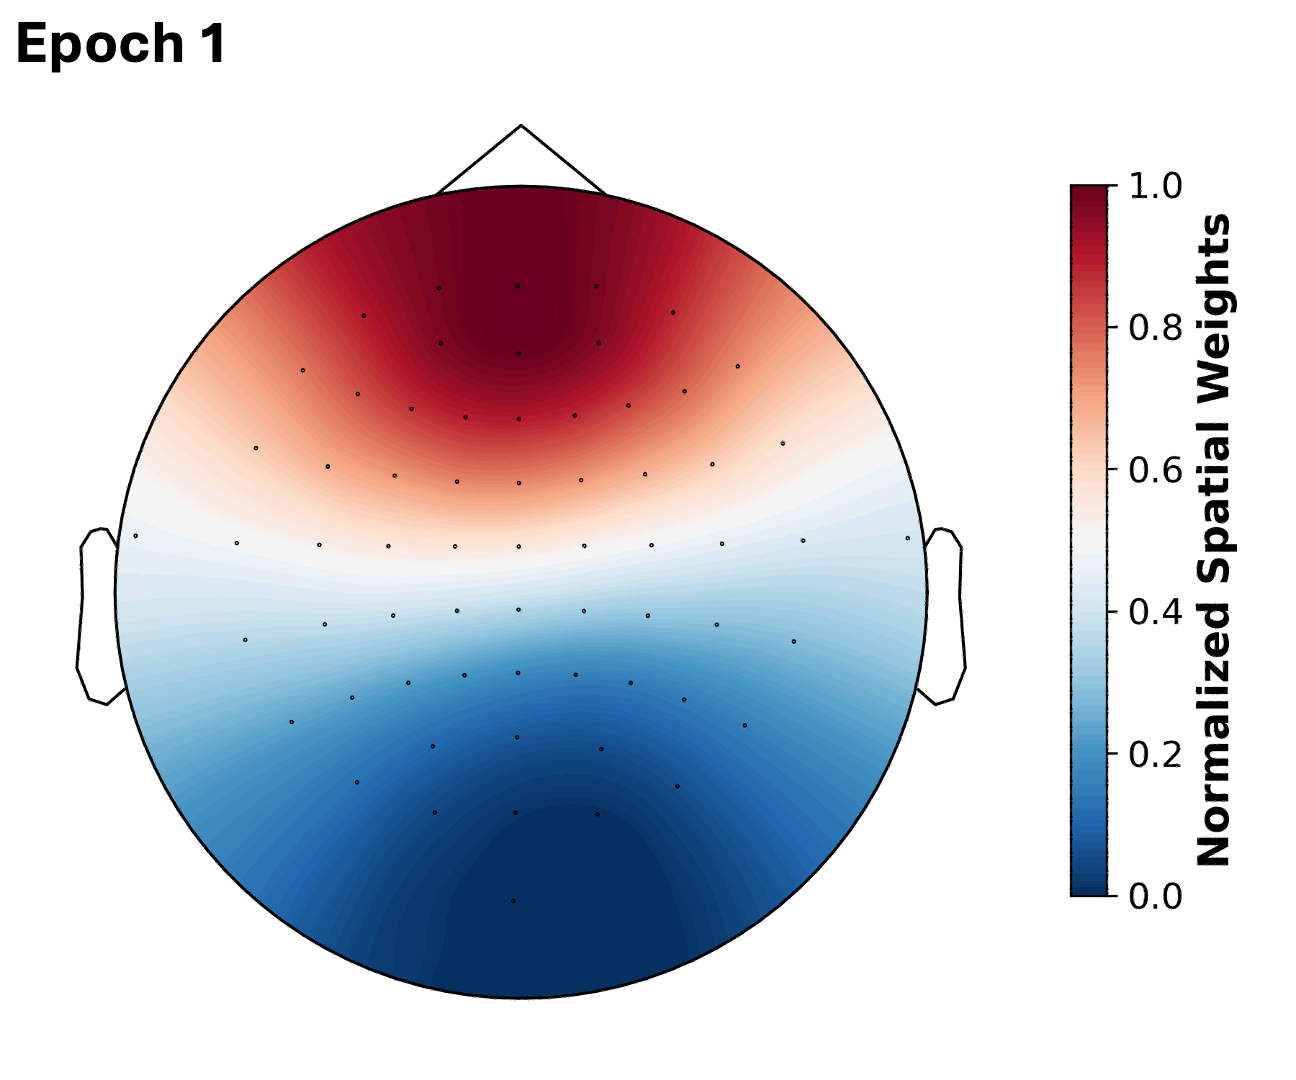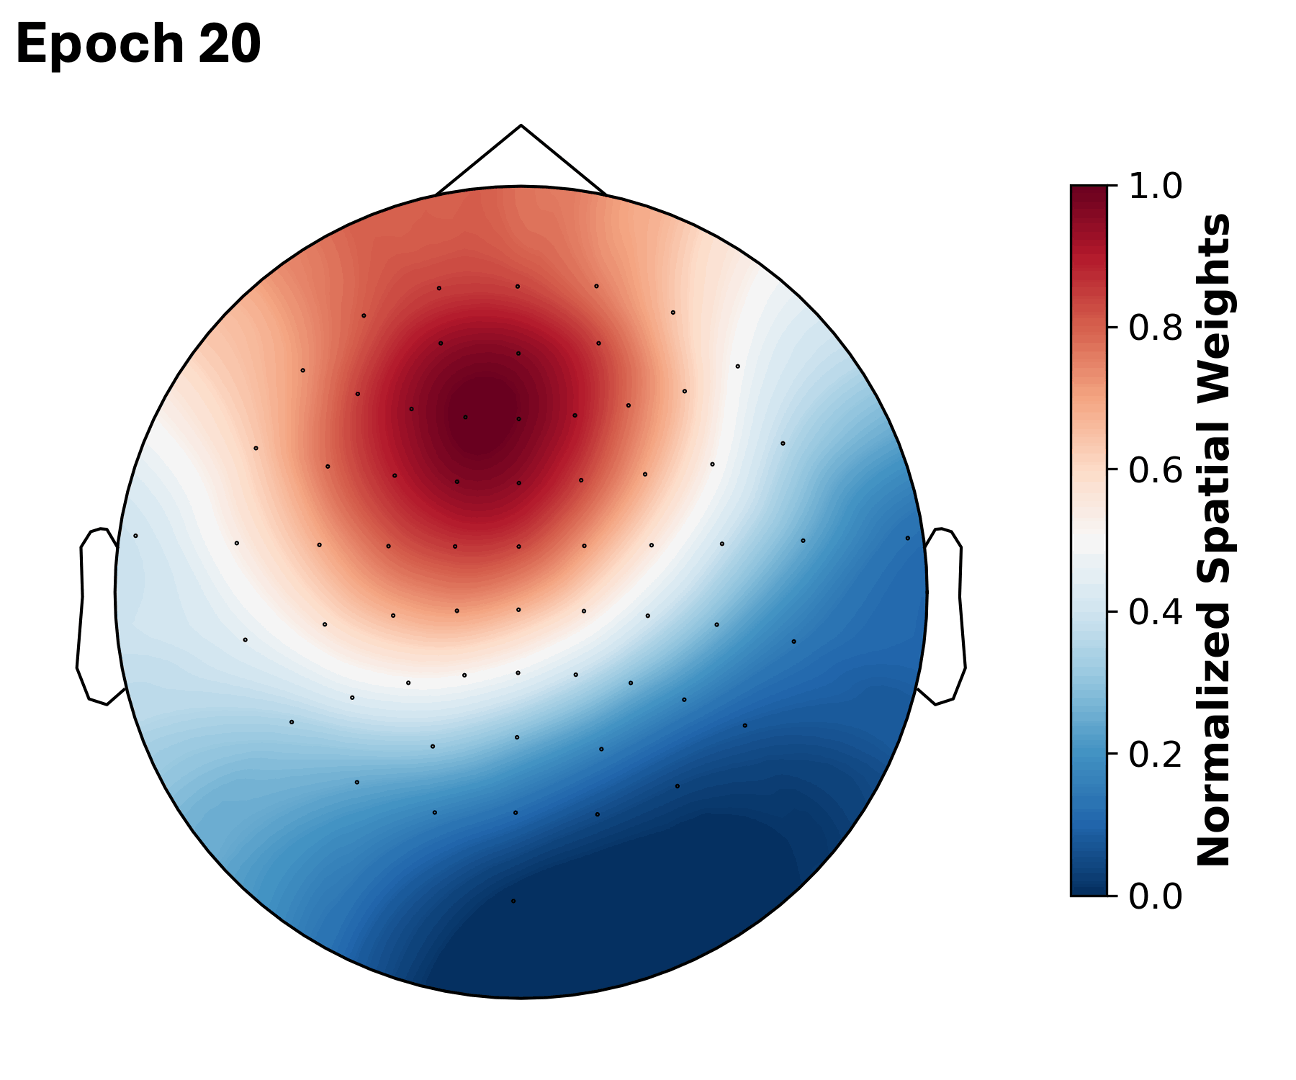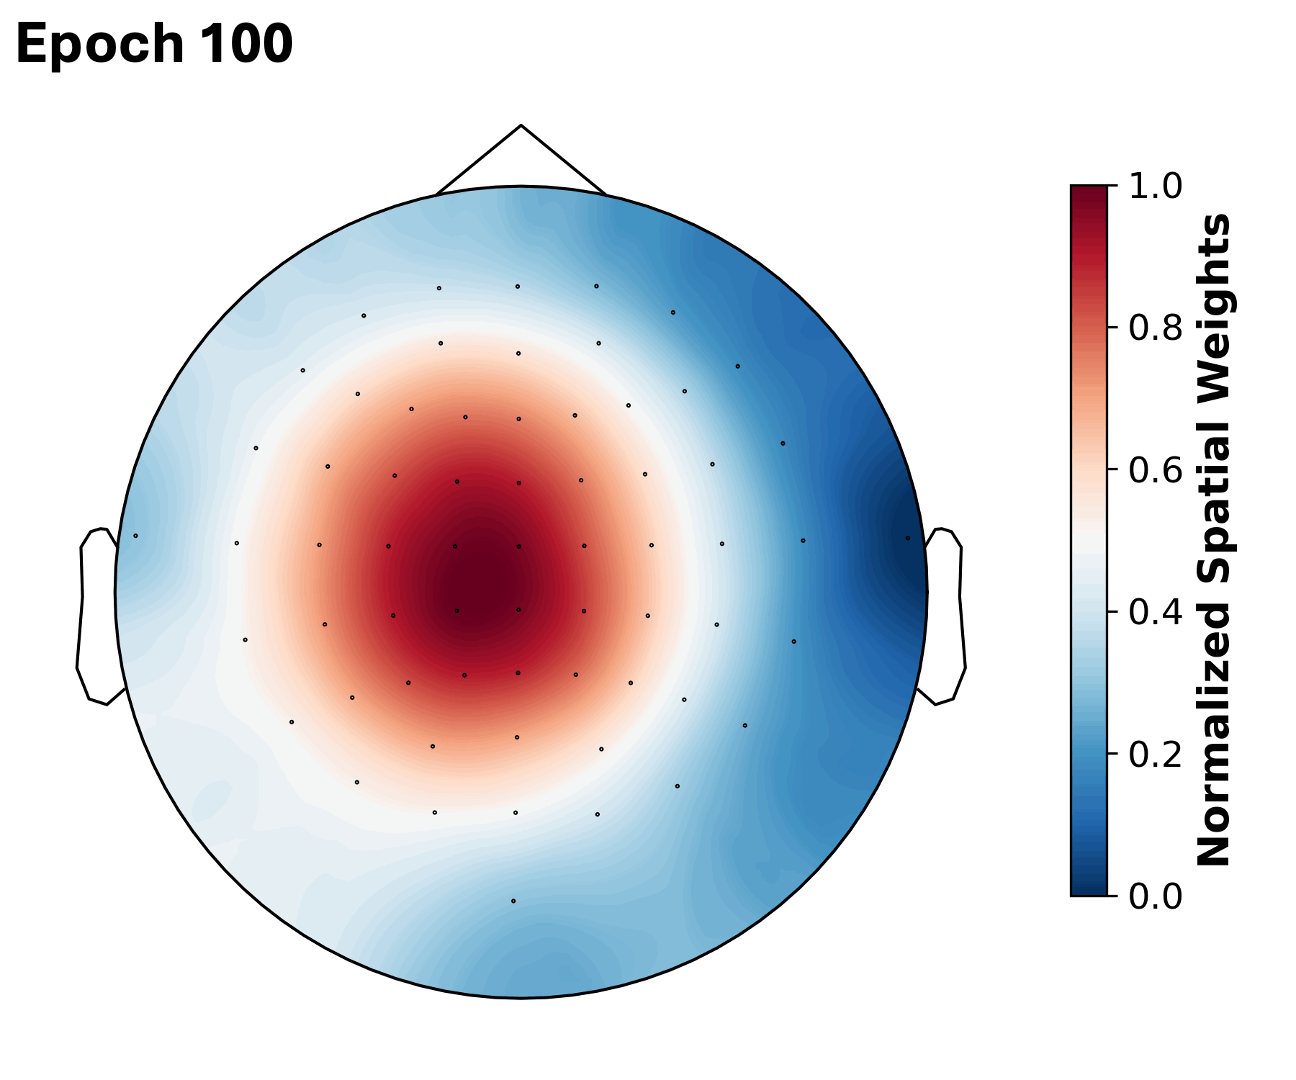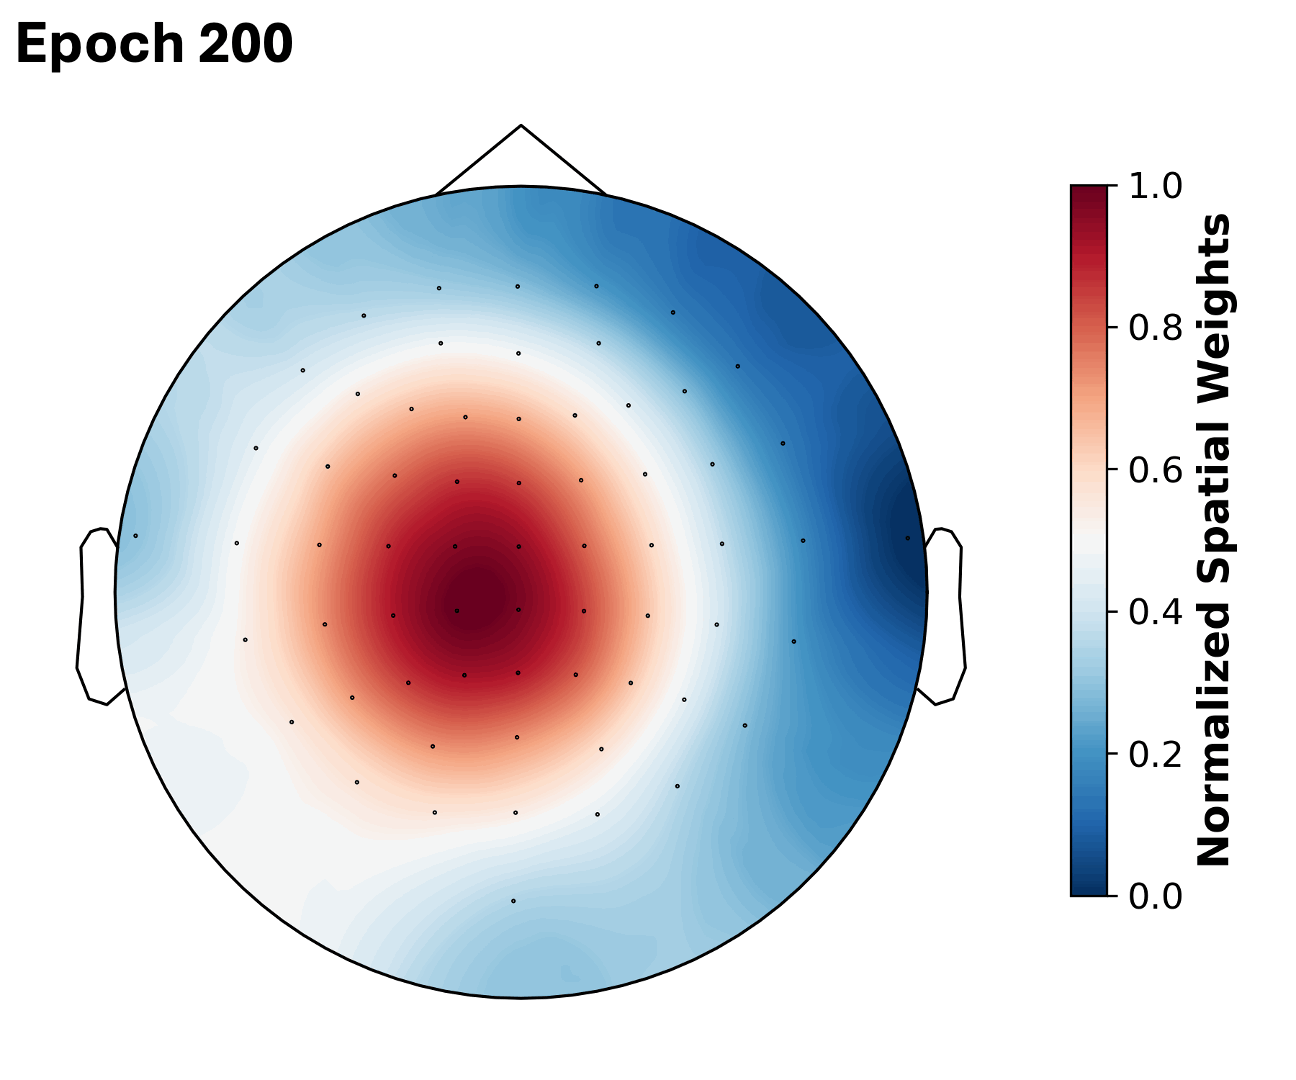 |
|
| 38 |
+
|
| 39 |
## Usage
|
| 40 |
|
| 41 |
Requires a compatible CUDA system.
|